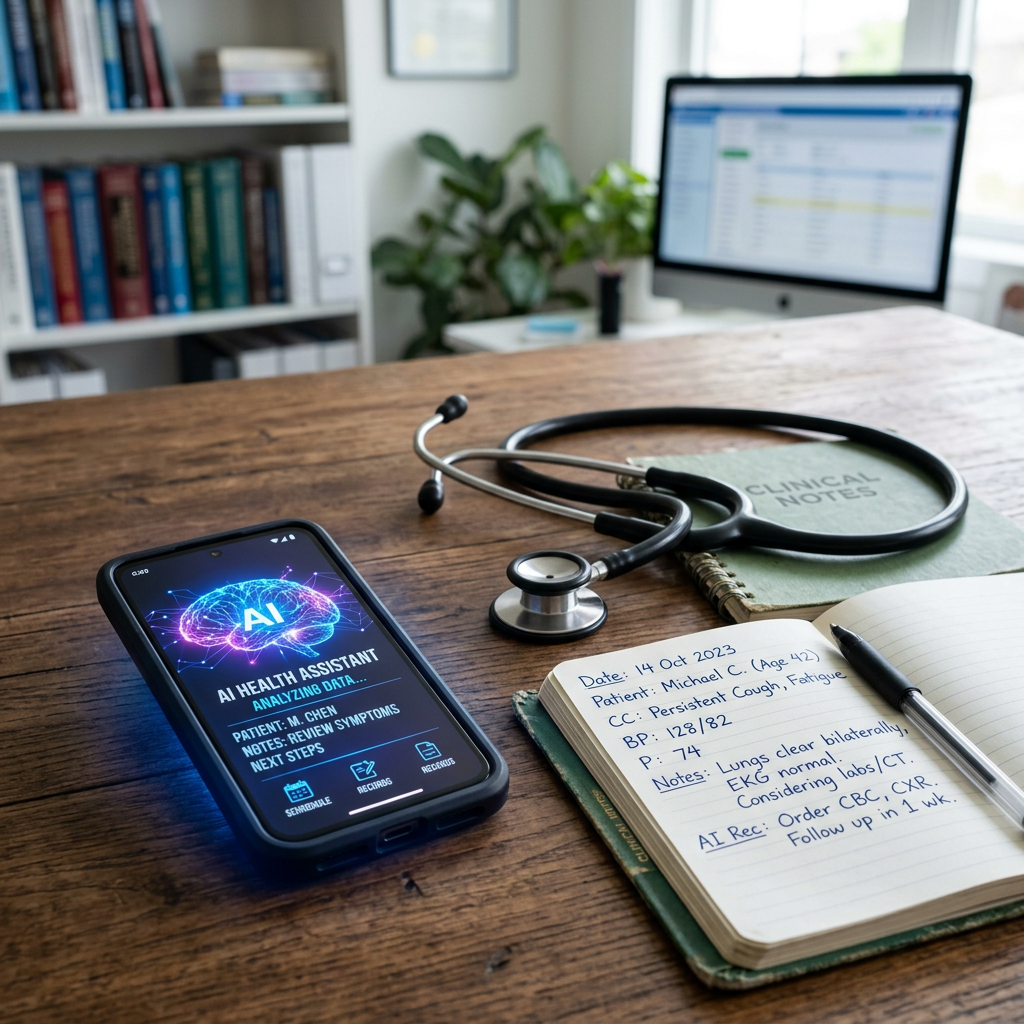
Testing six large language models on Choosing Wisely scenarios, Israeli researchers found low rates of overuse overall but high rates for EKGs and thyroid ultrasounds, and striking disagreement between models.
Not every medical test is a good idea. Unnecessary scans and procedures cost money, can expose patients to radiation or side effects, and often turn up harmless abnormalities that lead to more tests and anxiety. As more people turn to AI chatbots for health advice, a pressing question is whether those systems recommend too much care.
A study published in Annals of Internal Medicine suggests that, for the most part, they do not. Researchers from Ben-Gurion University of the Negev and Clalit Health Services in Israel found that six large language models usually recognized when a test or treatment was unnecessary. The exceptions clustered in areas where human experts themselves disagree.
“One of the hardest parts of practicing medicine is knowing when to hold back,” said Dean Ariel, a family physician and researcher at Clalit Health Services. He noted that patients can find comfort in an extra test, but that an unnecessary MRI, for example, often catches an asymptomatic disc bulge, a finding that can lead to needless worry and treatment.
Testing restraint
The researchers drew on Choosing Wisely, a campaign launched in 2012 by the ABIM Foundation in the United States to reduce low-value care. It has since expanded to more than 30 countries. Medical societies taking part identify tests and treatments that are commonly overused, such as imaging for uncomplicated low back pain.
The team built hundreds of clinical scenarios based on Choosing Wisely recommendations and tested six large language models from Google, Anthropic and OpenAI, generating thousands of responses. Each scenario in which an intervention was unnecessary was paired with a matched case in which it was actually needed. That design let the researchers measure two kinds of error: recommending care that was not needed, and withholding care that was.
“Language models learned medicine from human clinical literature—including our less disciplined habits,” Ariel said. “We wanted to see if they also absorbed the ability to exercise restraint.”
Mostly appropriate, with two exceptions
Overall, the models performed well. When care was unnecessary, they wrongly recommended a test or treatment in 5.4 percent of cases. When care was needed, they wrongly advised against it in only 0.6 percent. For 8 of the 15 Choosing Wisely recommendations studied, the models never recommended the unnecessary procedure.
Most of the overuse fell into two areas. The models recommended electrocardiograms for low-risk patients who did not need them in 28.3 percent of relevant responses, often when the patient reported palpitations. They recommended unnecessary thyroid ultrasounds for small, incidentally discovered nodules in 42.8 percent of responses, an area where professional bodies have issued conflicting guidance.
Both examples illustrate why restraint is hard. Palpitations can be frightening, and an EKG is quick and inexpensive, so ordering one can feel like the safe choice. Small thyroid nodules are extremely common and usually harmless, yet guidelines differ on when imaging is warranted, and detecting more nodules has been linked to a rise in diagnoses of small thyroid cancers that might never have caused harm.
“For the most part, they know when to stop, stumbling primarily where we doctors ourselves hesitate,” Ariel said.
No single AI voice
The models also differed sharply from one another in those gray areas. On identical cases, one model recommended an unnecessary test less than 10 percent of the time, while another did so 80 percent of the time.
“People often hear an AI chatbot speak in a single authoritative voice, as if there is a unified ‘AI consensus,’” said Guy Laban of Ben-Gurion University’s Department of Industrial Engineering and Management. The findings show that in contested areas, the advice a person receives may depend heavily on which chatbot they ask.
Laban also pointed to the social dimension of medical restraint. “Furthermore, telling a patient ‘you don’t need this test’ is a delicate social act,” he said. “A human physician must stand firm before an anxious patient,” he added, whereas language models tend to go along with the person in front of them.
The next test: pushback
That tendency, sometimes described as sycophancy, has been documented across many uses of AI chatbots, which are often trained in ways that reward responses users find agreeable. In medicine, it could mean that a model that correctly advises against a test might change its answer if a worried patient insists.
Laban said the next critical research question is whether an AI assistant will maintain appropriate clinical restraint when a patient pushes back. The current study tested single responses to scenarios rather than extended conversations, so it cannot answer that question.
The study, by Ariel, Laban and Stav Endelman of the Division of Dermatology at Rabin Medical Center–Beilinson Hospital, has other limits. The scenarios were constructed by researchers and may not capture the complexity of real patients. AI models are also updated frequently, so the behavior of specific systems may change. The release does not name the individual models tested.
Still, the results offer a more nuanced picture than either enthusiasts or critics of medical AI often present. The models appear to have absorbed much of medicine’s guidance on avoiding unnecessary care, but also its unresolved debates. Where doctors are uncertain, the machines are too, and they do not agree with each other.
Notes
- “Overuse and False Restraint in Large Language Model Recommendations for Choosing Wisely Scenarios.” Annals of Internal Medicine, 2026. DOI: 10.7326/ANNALS-26-01667.
- Ben-Gurion University of the Negev. “Does AI know when to say “no”? New study reveals AI chatbots recognize unnecessary medical tests.” EurekAlert!, 20 October 2026. https://www.eurekalert.org/news-releases/1148434.

Leave a Reply